AI-assisted research, source-checked and reviewed by a human editor. How we work
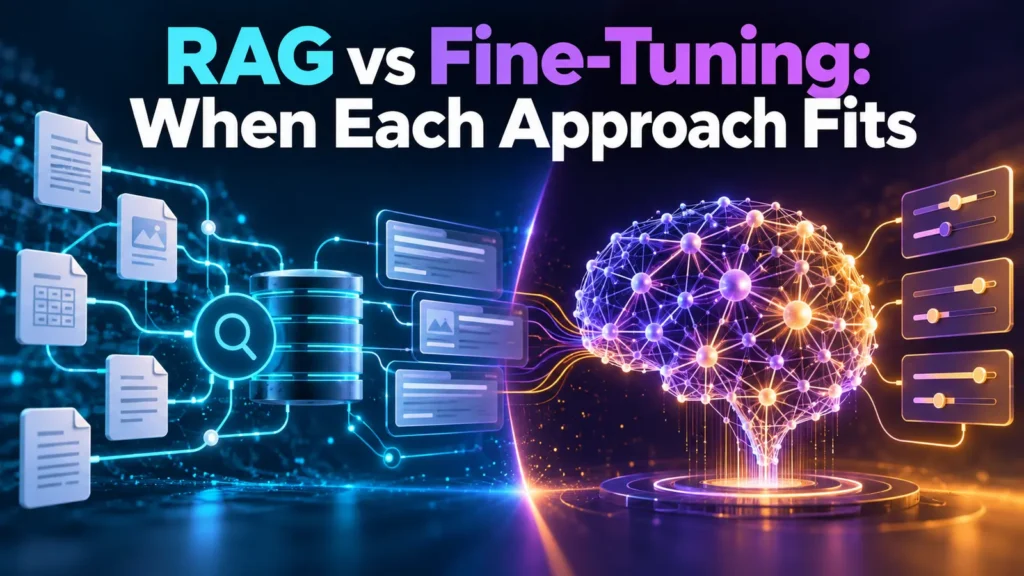
RAG and fine-tuning solve different problems. Retrieval-augmented generation supplies selected documents at answer time; fine-tuning adjusts a model through training examples. The decision depends on whether you need current facts, consistent behavior, traceable sources, or a combination of approaches.
Two different interventions
Retrieval-augmented generation supplies relevant external material at answer time, while fine-tuning modifies model behavior through additional training on examples. A company handbook question often calls for current document retrieval; a repeated need for a specific output pattern may benefit from examples or a fine-tuning workflow. Neither method guarantees truthful answers, and both require evaluation.
Choose retrieval for changing knowledge
When policies, product catalogs, or documentation change frequently, retrieval can connect an answer to updated source material without retraining model weights every time. The challenge shifts to ingestion, document access controls, relevance ranking, and faithful use of retrieved passages. A bad retrieval result can produce a plausible but wrong answer.
Choose fine-tuning for a demonstrated behavior gap
Fine-tuning may help achieve a consistent response style, format, or specialized task behavior when careful prompting and examples are insufficient. Training data must be representative and legally usable. It is generally not the simplest way to keep a rapidly changing private knowledge base up to date. Teams must evaluate whether a tuned model improves on a strong baseline rather than assuming more training is better.
They can be combined
An application can retrieve authorized records and use a model adapted for the required output structure. Combining methods increases complexity: data preparation, model versioning, retrieval quality, evaluation, and operating cost all need ownership. Start with the simplest system that passes your tests, then add components only when a measurable limitation justifies them.
A decision exercise
List ten real requests and the source of truth for each. If success depends on finding a current document, test retrieval first. If evidence is already available but the model repeatedly formats or classifies incorrectly, investigate examples and tuning. Check privacy, permission boundaries, error severity, and rollback before production use.
A practical architecture choice
For a handbook changing each month, retrieval can supply the current authorized source; fine-tuning alone is a poor substitute for retrieving changing policy. For a stable classification task with persistent formatting errors, tuning may merit testing after simpler prompts fail. Measure retrieval relevance, response fidelity, operating cost, and failure severity independently. A combined RAG and tuned-model stack creates additional components that must be monitored.
RAG versus fine-tuning: an application-first decision
Retrieval-augmented generation fetches information from a source collection at request time and supplies selected context to a model. Fine-tuning changes model behavior using additional training examples. That distinction helps teams avoid using expensive model adaptation to solve a document-management problem. Before choosing either, document the task, available source of truth, update frequency, and acceptable failure rate.
Example: current employee handbook
A company handbook changes each quarter and includes country-specific eligibility rules. A retrieval system can fetch relevant passages from the currently approved handbook, but only if its ingestion, ranking, and authorization controls work. The answer should link to its source and preserve exceptions. Fine-tuning on an earlier handbook could produce stale information and would not provide an adequate substitute for retrieving current policy.
Example: consistent classification output
A different team has an established classification taxonomy and a large collection of legally usable labeled examples. If simple prompting and examples cannot reliably produce the required categories, supervised fine-tuning may be worth evaluating. The team should compare it against an unchanged baseline on held-out data and measure whether improvements persist across difficult cases. Additional training is not automatically justified.
What to measure for retrieval
Measure whether the correct passages appear among the retrieved results, whether restricted content is excluded, whether document updates propagate, and whether answers faithfully reflect the supplied evidence. An apparently factual error may originate from a missing source rather than from the model’s reasoning. Test these components separately before adding complexity.
What to measure for fine-tuning
Assess response consistency, task accuracy, robustness on unseen examples, regression on previously working cases, and training-data provenance. Record model identifier, training settings, evaluation method, and ongoing maintenance needs. A tuned model can still hallucinate, misinterpret input, or fail on cases outside its training distribution.
Using both without unnecessary complexity
A tuned assistant might format responses consistently while retrieval supplies current authorized information. The combination requires separate ownership of model versions and indexed documents, privacy reviews for both paths, and monitoring of end-to-end failures. Start with the simplest baseline that satisfies the business requirement. For background, see our RAG explainer.
Decision record and stopping conditions
Ask whether the application needs new facts after source updates or mainly needs consistent output behavior. For changing facts, inspect retrieval freshness, citations, and authorization before training. For specialized behavior, make sure examples are representative and lawfully usable; compare tuning with an untuned baseline. If neither solves a measurable problem, do not add it. Keep a fallback for questions sources cannot answer. Neither architecture removes the need for human review.
Build a proof of concept that tests retrieval and tuning separately
A useful proof of concept should answer two separate questions: can the retrieval system locate the necessary evidence, and can the model accurately apply it? Save known-answer questions with approved source passages, including cases where no source supports an answer. Test stale document updates and permission changes. When considering fine-tuning, reserve evaluation examples that were not used for training, including rare but consequential edge cases. Compare quality and reviewer effort with a simple baseline and document added cost and maintenance. If the model fails because the relevant policy was never retrieved, tuning its style is unlikely to fix the underlying information gap. Teams should diagnose the source of failure before selecting an intervention.
Final verification scenario
When considering a hybrid solution, verify that the source retrieval layer and model adaptation are not solving the same issue redundantly. If the tuned model memorizes obsolete policy text, it may conflict with current retrieved passages. Test contradictory inputs and require answers to prioritize the authorized current source. For classification tasks, verify that tuning improvements are not confined to training examples or frequent categories. Measure operations and governance costs as well as apparent answer quality. An unnecessary architecture component can make a small team less reliable by adding another system to maintain.
Review notes
A further tradeoff involves auditability. Retrieval can often point to the current passage used to answer a question, although the answer still requires checking; a tuned response style does not provide the same source trail by itself. If traceable policy citations are a core business requirement, include them in acceptance criteria before choosing an architecture. Check whether the source document can be inspected by the intended user and whether the passage is current.
Frequently asked questions
Which approach helps with changing documents?
Retrieval is a common starting point when answers must reflect current authorized records.
Does fine-tuning automatically add up-to-date facts?
No. New source information generally requires a separate update or retrieval process.
Can the approaches work together?
Yes, with additional evaluation and maintenance complexity.
Sources and editorial method
This guide synthesizes primary reference materials and explains a general evaluation approach; it does not claim a hands-on vendor benchmark.
AI-assisted editorial draft. Human fact-check and publication approval required.