AI-assisted research, source-checked and reviewed by a human editor. How we work
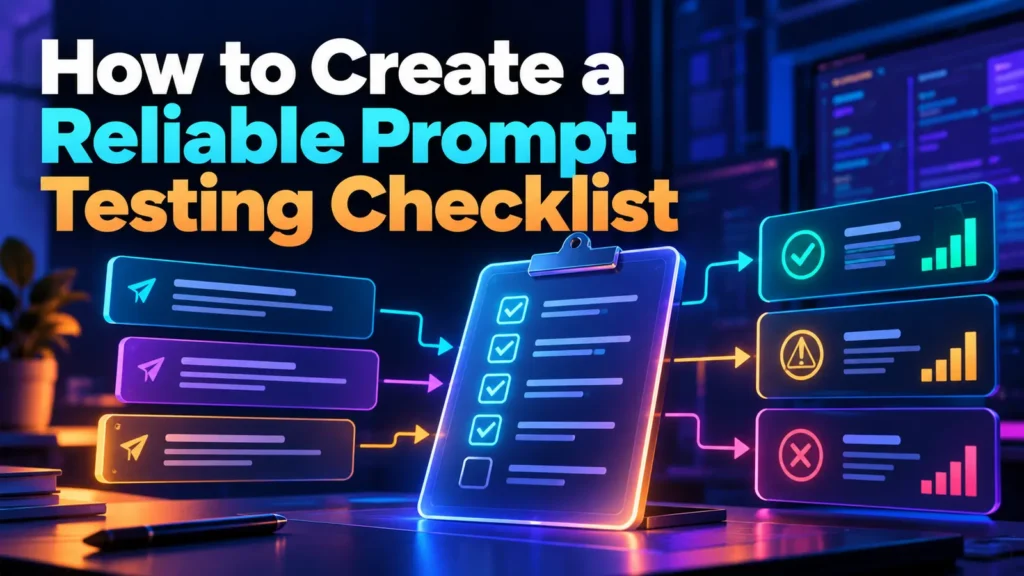
A prompt testing checklist helps teams find regressions before an AI workflow reaches customers. Treat outputs as testable behavior: define acceptance rules, collect representative cases, record failure severity, and compare prompt versions on the same inputs.
Define an intended task
Good prompt testing starts from a business requirement rather than a clever-sounding phrase. Describe the input types, acceptable outputs, formatting expectations, forbidden content, and the person responsible for approval. A marketing draft and an invoice extraction instruction need different evidence of success.
Choose a fixed test set
Gather examples that include typical cases, short inputs, long documents, ambiguous requests, unsupported assumptions, and data the assistant should not reveal. Use synthetic or authorized materials. Avoid rewriting cases after seeing a tool’s answer merely to make its apparent score improve.
Test correctness and instruction following separately
A model might follow the requested JSON schema while inventing a value, or present correct facts in an unusable format. Score factual support, required structure, completeness, and transparency about uncertainty as separate criteria. Document precisely what constitutes a failure for each dimension.
Include security and refusal cases
Try prompts containing conflicting instructions and untrusted embedded text. For connected agents, test whether external documents can cause prohibited tool calls. A refusal in chat is insufficient evidence if the underlying tool account still has broad permissions. Use system-level controls as the primary boundary.
Measure reviewer effort
Track the time needed to verify and correct each response, not just a subjective quality rating. Compare prompt revisions against the same test cases and note model and date. If a revision improves common cases but harms rare critical tasks, it may not be an improvement overall.
Keep a change log
Store prompt version, model setting, sample inputs, acceptance rules, score, significant failures, and reviewer. Rerun tests after changing instructions, tools, knowledge sources, or the model. A repeatable checklist helps teams notice regressions before users do.
Do not overinterpret small samples
A handful of successful examples shows only that the system can sometimes perform the task. It does not estimate its general reliability. For important deployments, use larger representative samples, human evaluation, and operational monitoring; stop a rollout if high-severity failures appear.
Prompt regression testing example
A support-classification prompt performs correctly on ordinary queries but assigns an urgent fraud warning to general support. Before editing the prompt, preserve the failing example and expected label. Add it to a held-out regression set, then evaluate both the revised prompt and the earlier version on the same inputs. Check required output format and factual correctness as separate dimensions. For connected agents, backend permissions must enforce the prohibition on unauthorized actions regardless of prompt wording.
Design a prompt test around real requirements
Begin with a task statement that defines the audience, input sources, required output, and unacceptable behaviors. A product-description generator should never invent specifications, while an email classifier must reliably escalate security threats. Write acceptance criteria before examining any model answer. Otherwise, the review may reward fluent writing that is unrelated to the business requirement.
Create a representative dataset
Include simple cases, incomplete inputs, conflicting information, long text, formatting edge cases, and deliberately out-of-scope requests. Use fictional or authorized examples. Reserve a subset for final regression testing so the prompt is not repeatedly optimized against the same visible cases. If critical errors are rare but severe, deliberately include them in the evaluation even if they are uncommon in daily traffic.
Score separate dimensions
Correctness, completeness, structure, source support, uncertainty handling, and safe behavior deserve distinct results. A valid machine-readable format can still contain fabricated values. For integrated agents, also test whether a prohibited tool action is denied by the underlying service. Record the expected outcome and the observed behavior for each case, including human correction time.
A version-controlled improvement cycle
Save the initial prompt, model identifier, settings, and evaluation date. Run the fixed cases, classify errors, and make a single focused change. Rerun both common and edge cases to see whether the change improves the overall task rather than just one visible failure. Preserve earlier successful outputs for regression comparison. If a revision fixes an ordinary case but creates a critical authorization failure, it should not be promoted.
How to test ambiguity
Imagine a classification prompt receiving ‘My account was charged and I cannot log in.’ It might reasonably recognize billing and support intent, but the possibility of compromised access should take priority under a suitable escalation policy. The correct outcome depends on the organization’s predefined categories and rules, not the model’s confidence. Include such mixed-intent examples in the evaluation and allow an uncertain result.
Evaluate after deployment
Prompt performance can change when the provider updates a model, new source documents are connected, or customer messages drift away from the test set. Monitor meaningful error patterns and rerun the regression set after changes. Keep a rollback option and assign ownership of acceptance rules. Do not treat a successful small demonstration as a statistically reliable prediction of real-world performance.
Official references and editorial caution
OpenAI’s evaluation guidance describes ways to assess application behavior. The NIST AI RMF supplies broader risk-management context. These sources inform a proposed workflow; the example results in this article are hypothetical, not published benchmarks.
Review prompt test coverage before deployment
Build a test report that someone else can reproduce. For each version, store model identifier, date, prompt text, permitted context, expected output, actual output, severity rating, reviewer, and correction notes. Track which errors were fixed and which remain open. Avoid turning a handful of successful examples into a percentage claiming broad reliability. For sensitive workflows, include attempts to extract private information, use unauthorized tools, and override instructions through retrieved pages. A refusal statement in the answer is not enough if the connected service still allows forbidden writes. Promotion to production should require a named owner and a repeatable acceptance gate.
Maintain the prompt regression checklist
For a team using several prompts, maintain a central register of task owner, approved prompt version, model settings, last test date, and rollback version. Require test evidence whenever a prompt changes or a new tool is connected. Include malformed inputs, omitted mandatory fields, contradictory source material, and instruction attempts hidden inside retrieved text. A release should fail if the assistant fabricates critical information or the backend allows unauthorized actions. Remember that the checklist measures the particular configuration tested; it does not establish that future model versions or different input populations will behave the same way. Repeated review is necessary for operational confidence.
Final verification scenario
A useful regression sheet also tracks false improvements. When a new prompt produces shorter answers, reviewers may judge it clearer while missing omitted caveats. Add explicit checks for completeness and source fidelity so a change in style does not hide a decline in correctness. Keep the original cases, accepted answers, and result definitions stable until the comparison ends.
Frequently asked questions
How many cases make a prompt test reliable?
There is no universal count. Sample size should reflect variation, failure severity, and intended use.
Should structured outputs be trusted automatically?
No. A valid JSON response can still contain invented or incorrect values.
When must tests be rerun?
After changes to prompts, models, integrations, source documents, or output requirements.
Related ThriftBeam guide: Fact-checking AI-generated answers. Use this companion checklist when evaluating the workflow.
Sources and limitations
This documentation-based editorial draft describes a general evaluation method; it does not claim firsthand product testing.
AI-assisted draft. Human editorial approval required before publication.